
From sea to screen: how eDNA Expeditions generates data you can trust
22 October 2026
How can we make sure that the data generated by eDNA Expeditions is reliable, transparent and can be trusted? By 2028, at the end of eDNA Expeditions 2026–2028, local teams will have collected over 3,000 water samples, generating hundreds of millions of DNA sequence reads. Before being made available, all that data must be assessed and verified.
Each identified sequence must be assigned a valid species name and quality-controlled, so that the data is trustworthy, standardized and transparent. To achieve this colossal task, the eDNA Expeditions team has designed a sea-to-screen data workflow built on a centralized digital backbone: the data management platform, which covers every step of the data integration process. Here is how a water sample becomes biodiversity data that researchers and decision-makers can trust.
In the field: collecting a sample
Sampling for eDNA
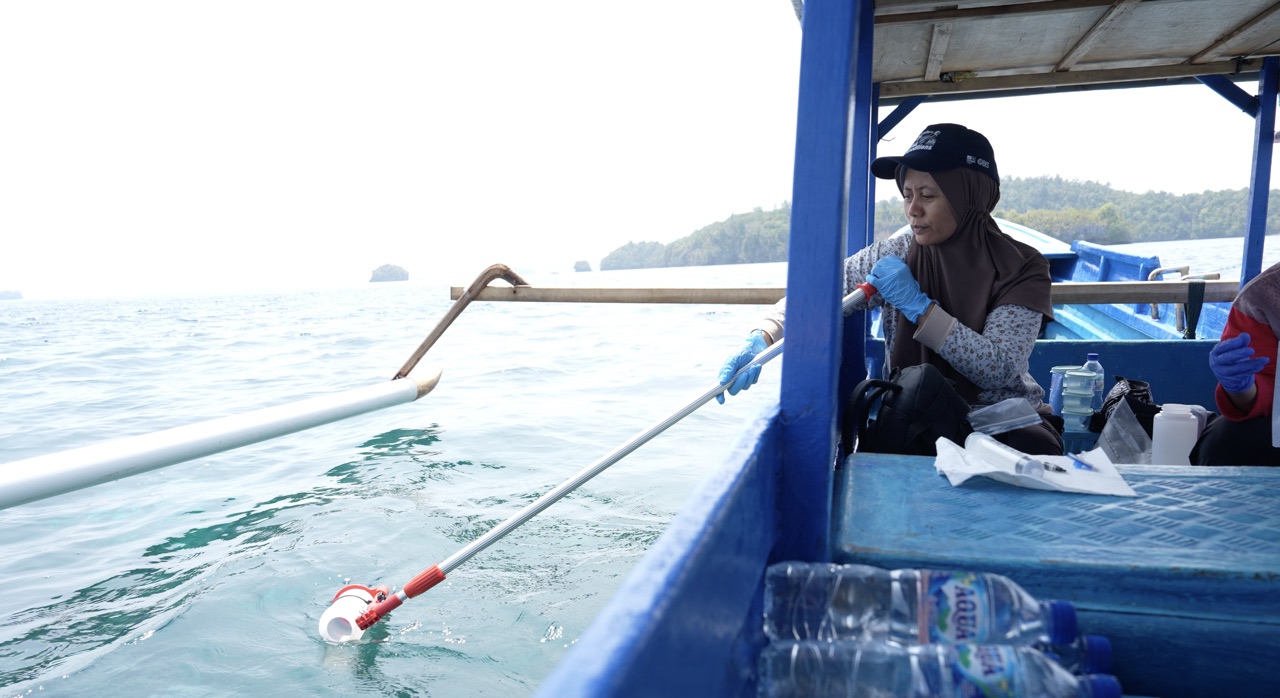
Local teams sample water to capture environmental DNA (eDNA), the genetic material left by marine organisms in their environment. This is where the whole data chain starts, so the quality of the sample, and the absence of contamination, is crucial. The sampling protocol, the training material, the guidance from eDNA Expeditions experts and the field-tested kit from Wilderlab all work towards an optimal sample.
Identify the sample
Each Wilderlab sampling kit comes with an identification number. Once a sample is completed, the team uploads its information to the dedicated eDNA Expeditions app, which automatically records the time, location and other properties of the sample along with the unique ID of the kit. Provenance is tracked from the source.
Persistent ID assignment
The app sends each sample record to the data management platform, where it is registered under a persistent ID: a unique number forever attached to that sample. The record follows the sample and is updated at every stage.
Putting a name on every sequence
The metabarcoding workflow
Identifying species reliably means comparing the collected DNA to reference information: known DNA sequences from characterised specimens, publicly shared through the International Nucleotide Sequence Database Collaboration (INSDC). Once sequence data reaches the platform, the OBIS team runs an open-source metabarcoding workflow, nf-core/ampliseq, which cleans the raw data and creates Amplicon Sequence Variants (ASVs), the distinct DNA sequences found in each sample.
Each ASV is then compared against the same reference databases using two methods, each with a different objective.
SINTAX: the broad view
Identifies the higher taxonomic levels, from kingdom to genus, by comparing short stretches of DNA called "k-mers" with the reference sequences, repeating the comparison many times to measure confidence at each rank.
Confidence is rated from 0 to 1 for each rank. Anything under the 0.8 cutoff is dropped.
VSEARCH: the strict check
Gives conservative species-level identification by aligning the sequence directly against each reference sequence in the database. Only sequences that are 100% identical to a reference sequence are given a species-level name.
If several exact matches point to different species, no species name is assigned and we fall back to the higher-level SINTAX classification.
Combining SINTAX and VSEARCH
Species-level assignments from SINTAX that VSEARCH does not confirm, the accession numbers of matching reference sequences, and the SINTAX confidence levels for every taxonomic rank are all recorded in the identificationRemarks field of the Darwin Core-formatted dataset, giving data users more context.
Final name alignment
Assigned names are automatically aligned to the taxonomy of the World Register of Marine Species (WoRMS).
Quality control: a combination of automation and human expertise
Automatic quality control
An automated tool assesses every identified record, and every identification receives a score based on two categories:
If a species is identified outside its known living area, or if the site temperature is outside its suitable range, the identification gets a low score and is highlighted on the list. A low score might mean a misidentification, or it could be a real discovery: a newly arrived invader, a species expanding its habitat, or a species thought to be locally extinct.
Manual quality control
Local experts support the review of flagged records. They can confirm, question or correct each identification. Their decisions carry through to the data published on OBIS and are recorded in the identificationRemarks field. The data is then delivered in Darwin Core format, ready for publication.
On screen: data that anyone can use
Making the data available
The data is standardized under Darwin Core, a community-validated format that allows comparison and interoperability. A sample taken in Cameroon can be compared with one taken in the Philippines, and the data is ready to use on large biodiversity platforms such as OBIS and GBIF.
Importantly, the original data provider keeps ownership of the published data: thanks to persistent identifiers, users can trace back the author(s) of a dataset.
eDNA Expeditions 2026–2028 aims at one thing: making change happen. The initiative gives local teams the high-quality biomolecular data they need to better manage and protect their waters, and provides local communities and site managers with data they can rely on. If successful, it can pave the way to an even more ambitious project: a future global biomolecular marine biodiversity observation network.
Dive deeper
- Ocean Biodiversity Information System (OBIS)
- Global Biodiversity Information Facility (GBIF)
- World Register of Marine Species (WoRMS)
- nf-core/ampliseq
- Stay informed, join our newsletter (scroll below!)